Blogs / LLMs & agents
What Is an Agent Harness? The Layers Around the Model That Make AI Agents Work
By Kadam Parikh · · 23 min read · Updated · Worked example: a room-planning agent with a 3D view
The same model can look brilliant or useless depending on what surrounds it. This is what that surrounding code, the agent harness, contains, shown on a room-planning agent I built and then tested over 60 runs.
The same model, different results
When an AI agent fails, the instinct is to blame the model and wait for a better one. The evidence says to look elsewhere first. LangChain took a coding agent and changed only the code around it, with the model fixed. Its score on Terminal Bench 2.0 went from 52.8% to 66.5%. The changes were not exotic: a prompt that makes the agent verify its work before it finishes, an up-front summary of the project’s folders so it does not have to search for them, a warning when it keeps re-editing the same file, and a different split of how much thinking effort it spends on planning versus checking.
That surrounding code has a name, the harness, and building it well is becoming a discipline of its own. This post explains what is in one, layer by layer, and uses a small agent I built to make each layer concrete.
What is an agent harness?
An agent is a language model in a loop: it looks at the situation, picks an action, sees the result, and repeats until it decides it is done. The harness is the program that runs that loop. It decides what the model sees, which actions exist, what happens when an action fails, when the loop ends, and what gets recorded.
The usual short definition is “everything except the model”. It is true, but a writer at Futurice points out that it only says where the harness ends, not what it must contain. I find it more useful to define the harness by its parts, and the six layers below are those parts, in the order you meet them when building one.
The worked example: a room-planning agent
I built an agent that places furniture in a bedroom. The room already has its door and window, as any built room does; the agent’s job is only to decide where the furniture goes. It gets the room’s size, where the door and window are, and a catalog of furniture items with varying sizes. The model proposes a position for one item at a time, and a proposal the checker turns down is called a rejection. The hard rules are simple to say and easy for a model to get wrong: nothing overlaps, nothing leaves the room, nothing blocks the door or window, every piece touches a wall, and its width runs along that wall.
The pattern, where the model proposes and ordinary code decides, is the same one behind another project of mine, an AI that plans a video while ordinary code builds it. This is exactly where a model needs a harness. It is good at the design judgment (the bed goes against a wall, a side table goes beside it) and unreliable at coordinate arithmetic. Here is the whole loop:
1 · Set up
- The roomsize, door and window; plus a catalog of furniture items to place
- Door and window as obstaclesfurniture may not overlap or block them
2 · Propose
- Modelone item: position and size
3 · Check
- Checker, five rulesoverlap, openings, room bounds, wall contact, wall alignment
4 · Respond
- Validitem added to the layout
- Invalidthe specific reason goes back to the model, which retries
And here is one real result. It is a layout the planner produced in one of my test runs, drawn in 3D. Drag to rotate, then switch to “Boxes the checker sees” to see what the checker actually reasons about: five boxes, a door and a window.
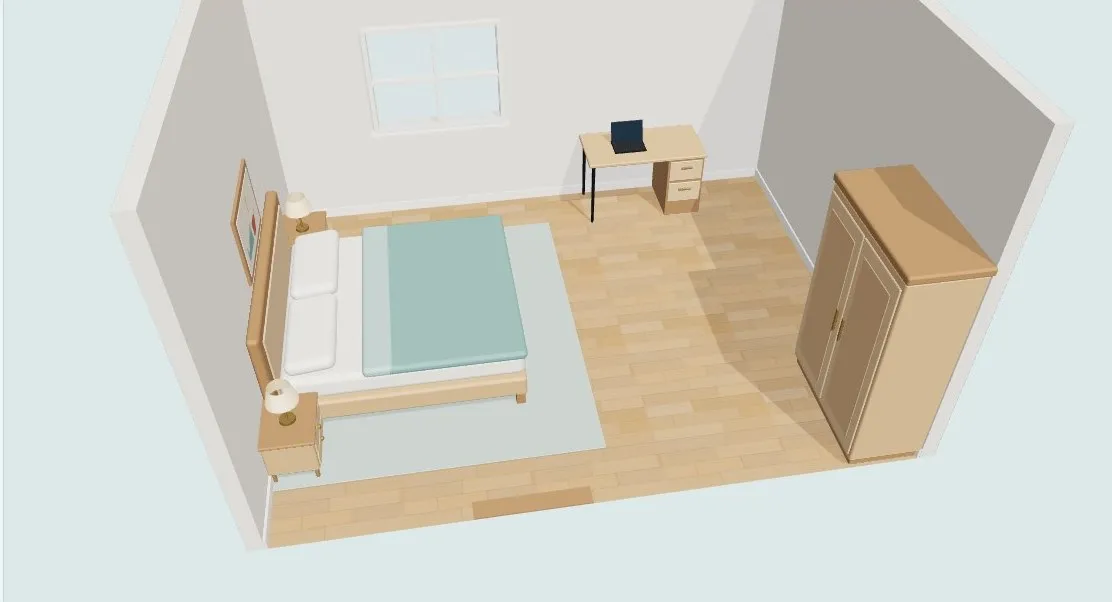
A bedroom seen from above and slightly south-west. A bed with a tall headboard stands against the west wall with a nightstand on each side. A wardrobe stands against the east wall near the south corner, a desk sits against the north wall, and a door is in the south wall.
Three versions of the harness
To see what each layer is worth, I ran the planner three ways on the same bedroom, 60 runs each (two batches of 30), with Claude Haiku as the model and the planner’s original prompt and checking code. The versions differ only in how the checker behaves:
- No checker. The tool accepts every proposal. Afterwards I audit each layout against the same five rules to count the breaks.
- Vague rejections. The same five checks, but a rejection says only “Invalid.”
- Specific rejections (the planner as built). A rejection names the broken rule and the item involved.
A layout counts as valid and complete when all five items are placed and no rule is broken. I ran the comparison twice, so the table adds both batches together and shows the two separate counts in brackets (first batch + second batch). Here is how each version did:
| Harness version | Valid, complete layouts | Rejections | Model calls per layout |
|---|---|---|---|
| No checker | 43 / 60 (23 + 20) | n/a | 5.0 |
| Vague rejections | 59 / 60 (29 + 30) | 55 (26 + 29) | 5.9 |
| Specific rejections (as built) | 60 / 60 (30 + 30) | 15 (5 + 10) | 5.3 |
The sections below use these names and refer back to this table.
The layers of a harness
Six layers cover most of what a harness does. Each one starts with what the layer is for, then what published guides from Anthropic, LangChain and Futurice recommend, then what it looked like in my room planner. Two layers are easy to confuse. Guardrails stop a bad action before it takes effect; verification judges the finished result afterwards. Layers 4 and 5 show the difference on the same example.
1 · The loop
The loop is the cycle of “the model picks an action, the program runs it, the model sees the result”. This layer decides when the cycle ends.
What the guides say. Anthropic separates workflows, where your code fixes the order of the steps, from agents, where the model chooses the steps itself. It advises starting with the simpler workflow and adding agent-style freedom only when it measurably helps. LangChain added a guard for a common failure: a coding agent that keeps re-editing the same file without getting anywhere. After a set number of edits, the harness tells it to try a different approach.
In my room planner. The cycle is: the model proposes a placement, the checker answers, repeat. It ends when the model stops asking. In my tests I also stopped any run after 12 proposals, so a model that gets stuck cannot loop forever. Only one of the 180 runs reached that cap.
2 · Tools
A tool is a function the model can ask the program to run, such as “place this bed here”.
What the guides say. Anthropic recommends a few well-designed tools over one tool for every possible action. It also says to write error messages for the model: say what was wrong and how to fix it, not an error code.
In my room planner. My first version had three tools (validate a placement, suggest another position, check the entrance is clear) and became hard to debug. I rebuilt it around one tool that checks a placement and saves it if it passes. The checks inside it come back under guardrails; the point here is what the tool says when it rejects a placement. The reply names the broken rule and the item involved:
# Abridged from the planner's one tool. The model never sees `state`.
overlap, other = check_overlap(proposed, state["placements"])
if overlap:
    return f"Invalid: Overlapping with {other}."

walls = get_touching_walls(proposed, state["room_dimensions"])
if not walls:
    return "Invalid: Furniture must touch a wall."
if not check_width_alignment_with_walls(proposed, item_info, walls):
    return f"Invalid: Width must align with one of the touching walls ({', '.join(walls)})."

state["placements"].append(proposed)   # only valid placements are ever stored
return "Valid: Furniture placed successfully."
How much does that reply matter? With vague rejections, where the reply is only “Invalid.”, the model was rejected 55 times across the 60 runs. With specific rejections it was rejected 15 times, about a quarter as often. Same model, same checks; the vague version simply gave it nothing to correct from.
3 · Context and state
Context is everything the model can read at one time. State is what the program remembers between steps.
What the guides say. A model gets less accurate as its context fills up, so Anthropic suggests, among other techniques: summarise the old conversation (called compaction), keep notes in a file outside the context, and hand a side task to a sub-agent, a second model call with its own clean context that returns only a short summary. For work spread over many sessions, they had agents keep a checklist of required features, each marked “failing” until tested, plus a progress log and git commits, so each new session can see where the last one stopped.
In my room planner. The conversation is short, so it needs none of that. Its state design is simpler. The program holds the layout, and the model sees only the checker’s replies, so it cannot edit the layout directly. And the model proposes one piece at a time, so every check sees all the earlier placements.
4 · Guardrails
A guardrail is a rule enforced by ordinary code before an action takes effect, so the result does not depend on the model obeying instructions.
What the guides say. Futurice describes the pattern: the model only proposes an action, and the harness checks it against the rules before anything happens. Their phrase for it is “The model proposes; the harness disposes.” In their examples, actions are denied by default, and riskier ones, such as deploying code, are held to stricter rules.
In my room planner. The five placement rules are guardrails. Each proposed placement is checked before it is saved, so a bad one never enters the layout. Two of the rules, “a piece touches a wall” and “its width runs along that wall”, started in the prompt and moved into the checker. The no-checker version shows why: 17 of 60 layouts broke a rule. Of the 30 individual breaks, 28 were one of those two rules and two were overlapping pieces. Blocked openings and pieces outside the room never happened with this model. The subtle rules are the ones worth moving into code.
5 · Verification
Verification means judging the finished result against something the agent cannot influence.
What the guides say. Anthropic found that agents often declared a feature done after a quick unit test, without confirming it worked from a user’s point of view. Giving the agent a real browser to test with helped a lot. Futurice’s rule: “the agent may verify, the harness must witness”. Evidence only counts if the harness collected it.
In my room planner. The checker looks at one placement at a time. Nothing judges the finished layout as a whole, so if the model quits with the desk unplaced, nothing notices. The no-checker version shows the gap from the other side: I audited each layout afterwards and found 17 of 60 broken, but an audit after the fact cannot repair them. For the tests I wrote a separate check that counts missing items, and my script decides a run is complete by counting what was accepted, not by the model saying it is done. That check is verification. The five rules in the loop are guardrails.
6 · Observability and evals
Observability means recording what happened in each run. An eval is a repeatable test that scores the agent over many runs.
What the guides say. Anthropic’s multi-agent team notes that “agents are stateful and errors compound”: one early mistake changes everything after it. So you need a full trace of every step to see where a run went wrong.
In my room planner. I record every model call and checker reply in a tracing tool (Langfuse) and save a top-down image after each accepted placement, so a run can be replayed step by step. What the planner lacked was an eval: no set of test rooms and no pass rate. My last commit note on reliability said only “does not work at times”. The script behind the three-version comparison above is a small eval harness in the sense defined earlier, and it is the first measurement the planner has had.
Agent harness vs guardrails vs eval harness
These terms are used interchangeably in a lot of writing, and they are not the same thing. The quickest way to separate them is by the question each one answers. Guardrails are part of the agent harness, not an alternative to it, and the eval harness sits outside both.
| Term | What it is | The question it answers | When it acts | In the room planner |
|---|---|---|---|---|
| Agent harness | The whole program around the model | How is a run coordinated? | During every run | Loop, one tool, state, logs |
| Guardrail | A rule enforced in code before an action takes effect | Is the agent allowed to do this? | Before each action | The five placement rules |
| Verification | A judgment of the finished result against evidence the agent cannot influence | Is this result actually right? | At the end of a run | My test script counting missing items |
| Eval harness | A test setup that runs the agent many times and scores it | How well does the agent perform overall? | Outside production, before and after a change | The comparison script, run 60 times per version |
Guardrails vs the harness
A guardrail is one layer of the harness. A harness with no guardrails still has a loop, tools and logs; it just lets every action through. When someone says “we added guardrails”, they have added rules to the harness, not replaced it.
Guardrails vs verification vs evals
All three are checks, but they act at different moments. A guardrail prevents a bad action. Verification catches a bad result before it reaches the user. An eval measures how often either one was needed. Arize draws the same line between guardrails and evals: an eval can tell you a failure happens, but only a guardrail stops it from happening in front of a user. In my planner, the five placement rules are guardrails, the missing-item count is verification, and the 60-run comparison is the eval.
Agent harness vs eval harness
The agent harness serves users; the eval harness measures the agent harness. An eval harness runs your agent on a fixed set of test cases several times each, grades every result and reports a pass rate. Keep them separate, and note which version of each produced a score: a number can move because the model changed, the agent harness changed, or the grading changed. If you want a larger example of measuring an LLM pipeline instead of trusting it, see my case study Measuring an LLM insight pipeline.
One more source of confusion: “evaluation harness” also names an older kind of tool, a benchmark runner that scores models against public datasets. That is a test of models, not of your agent.
Tool or prompt? How to decide when the model is strong
The common objection is: “our model is large and reasons well, so why build a tool or a checker for something it can already do?” It is a fair question, and the answer is not “always build one”.
Short answer. Put a rule in code when it must hold every time, when a mistake is costly, or when the model cannot see the information. Leave it in the prompt when it is judgment and several answers are acceptable. A stronger model lowers the failure rate; it does not set it to zero. A failure that happens in 1 run in 20 is easy to miss in a demo and shows up daily in production.
First, do you need an agent at all?
Before choosing between a tool and a prompt, ask whether one well-written model call solves the task. If it does, stop there. Tools only help when the model needs something a prompt cannot give it: data it cannot see, exact computation, state that outlasts one call, or an action with side effects. A fixed sequence of steps in your own code is also still an option; an agent is only needed when the model has to choose the steps.
Measure it instead of guessing
My no-checker test is the method. I let the model place furniture with nothing enforcing the rules, then audited every layout. Of 60 layouts, 17 broke a rule. Of the 30 individual breaks, 28 were one of two rules: a piece must touch a wall, and its width must run along that wall. The other two were overlapping pieces, and blocked openings and pieces outside the room never happened. So the model was reliable on most rules and unreliable on two. Those two clearly needed to move into code.
One caveat: the model in that test was Claude Haiku, a small one. A larger model would probably break fewer rules, and I have not tested that. The method still transfers. Run your agent with no tool or check, N times, audit each result against the rule, and count the failures. The count tells you whether the rule belongs in the prompt or in code.
A decision guide
| Situation | Put it in | Why |
|---|---|---|
| Exact arithmetic, geometry, counting, date maths | A tool or checker | There is one right answer, and models make small errors in exactly this kind of work |
| A rule that must hold every time | A guardrail in code | The result should not depend on the model choosing to obey |
| An action with side effects: send, deploy, delete, pay | A tool with a permission check | The harness should be able to refuse before anything happens |
| Information the model cannot see: live data, private records, the program’s state | A tool | No amount of reasoning replaces access |
| Anything you must be able to audit afterwards | A tool | A tool call is logged; a thought is not a record |
| Judgment, taste, tone, ambiguity | The prompt | There is no single right answer, so code would be brittle |
| A rule the model followed every time in your own test | The prompt, plus a cheap check if a failure would be costly | The measurement says the prompt is enough; the check is insurance |
Check, don’t compute
A tool does not have to take over the job. In my planner the model still chooses every position. The tool does not compute a placement; it only accepts or rejects one and says why. That keeps the model’s design judgment and removes its arithmetic errors. If you are unsure whether to build a tool, a checker is usually the smaller, safer step than a tool that does the work for the model.
Signs you have too many tools
Anthropic’s advice on tool design is a few well-designed tools, not one per possible action, because tools that overlap make the model’s choice harder. A tool that only wraps something the model already does reliably adds a step, extra tokens and one more thing that can fail. A 2026 research paper, “LLM Agents Already Know When to Call Tools”, reports that tool-using agents often call a tool when they could have answered directly, which wastes cost and time. My first planner had three tools and was hard to debug; one tool replaced them.
Signs you need one
These are my rules of thumb, not published findings. You probably need a tool or checker when the prompt keeps growing with “always” and “never”, when a fix to the prompt brings back an old bug, or when you cannot tell from the trace whether a rule was followed. The practical path is the one I took: start with the prompt, measure, and move the rules that fail into code.
What is loop engineering?
Loop engineering is a new and loosely defined term, and writers use it in slightly different ways. What most share is this: it means designing the repeating cycle around an agent, including what starts a pass, how each pass is checked, what counts as progress, and what stops the run.
It helps to separate two loops:
- The inner loop is the cycle inside one run: the model picks an action, the program runs it, the model sees the result. This is layer 1 of the harness.
- The outer loop repeats whole runs until something outside the model says the work is done, such as running an agent again until the tests pass, or on a schedule. Several write-ups, including one from Analytics Vidhya, place this on top of the harness. The harness equips one agent; the outer loop decides when it runs again and whether its work counts.
Four decisions come up in either loop, and each has an example earlier in this post:
- A stop rule. What ends the run, and what ends it if the model never finishes? My test cap was 12 proposals per run.
- A feedback signal outside the model. A loop that only asks the model whether it is done will repeat its own mistakes. My script counts accepted placements instead of trusting the model’s “done”, and LangChain’s harness tells a looping agent to change approach after repeated edits to one file.
- A budget. Every pass costs tokens and time, so cap the number of passes and the spend.
- State between passes. A later pass needs to know what an earlier one did. Anthropic’s long-running agents leave a progress file and a feature checklist for exactly this.
Seen this way, loop engineering is not a replacement for harness engineering. It is the part of it that deals with repetition and stopping.
Going multi-agent: what changes
The planner is a single agent, and I have not built a multi-agent version of it, so this section draws on Anthropic’s published experience instead of mine.
Moving to several agents does not replace any layer; each agent still needs its loop, tools, context and checks. It adds three problems:
- Hand-offs need a contract. In Anthropic’s research system, a lead agent plans a question and sends searches to several worker agents. Vague instructions made workers repeat each other’s work, so each one was given a goal, an output format, which tools to use and where its task stops.
- Effort needs a rule. Early versions launched 50 workers for simple questions. The fix was to put sizing rules in the lead agent’s prompt: one worker for a simple lookup, a few for a comparison, many only for open-ended research.
- Failures compound, so they must be recoverable. A long-running agent builds on its own earlier steps, so one failure can spoil everything after it. The team made runs resumable from the point of failure instead of restarting, using retries and saved checkpoints.
The payoff is real but narrow. The same system, a lead agent with workers, beat a single agent by 90.2% on Anthropic’s own research test, but used roughly 15 times as much text (measured in tokens, the units models are billed by) as an ordinary chat. They say it suits broad questions that split into pieces done at the same time, and suits poorly any task where the agents must share the same information or depend heavily on each other. They note that most coding tasks split less than research does.
By that guidance, my planner would be a poor candidate for splitting: each placement depends on every earlier one, so separate agents would have to share everything anyway. That is my reading of their advice, not a test. It does fit the earlier point: add agents when the work demonstrably splits, and spend the effort on the harness first.
A checklist for your own harness
Use these questions on an agent you are building or buying. The right-hand column shows how the planner answers them.
| Layer | Question to ask | The room planner |
|---|---|---|
| Loop | What ends a run, and what happens if the model never finishes? | Ends when the model stops calling the tool; capped at 12 proposals in the test |
| Tools | Is each tool necessary, and does a failure say how to fix it? | One tool; rejections name the rule and the item |
| Context and state | What does the model see, and what must it never touch? | Short context; the layout is held by the program and hidden from the model |
| Guardrails | Which rules does code enforce before an action takes effect, rather than the prompt? | Five placement rules, checked before each placement is saved |
| Verification | Who judges the finished result, and can the agent influence that judgment? | Not built into the planner. My test script counts missing items and audits each layout |
| Observability and evals | Can you replay a run, and do you have a pass rate? | Traced and replayable; pass rate measured only in the test above |
Frequently asked questions
What is an agent harness in simple terms?
It is the program that runs an AI agent: the loop, the tools the model can call, what the model sees, the rules enforced in code, the checks on the result and the logs. The model is the engine; the harness is the rest of the car. A common shorthand is “agent = model + harness”.
Is an agent harness the same as an agent framework?
Not quite, at least in how I use the words. A framework is a library that supplies reusable parts such as a loop runner and tool wiring. The harness is the assembled system that runs your agent, including your own tools, rules and checks. You can build a harness with a framework or without one.
Is orchestration the same as a harness?
No. Orchestration sits above the harness: it decides which agent gets a request, passes information between agents and combines their results. Each of those agents still needs its own harness. The multi-agent section covers what changes.
Do I still need a harness if my model is very capable?
Yes, but a stronger model changes which rules need code, not whether you need a loop, state, permissions and logs. LangChain’s 52.8% to 66.5% result came from changing only the harness with the model fixed. See tool or prompt for how to decide what to move into code.
How is harness engineering different from prompt engineering and context engineering?
Prompt engineering is the wording of the instructions. Context engineering is choosing what is in the model’s window at each step. Harness engineering includes both and adds everything that runs outside the window: the loop, tools, guardrails, verification and logs. Prompts and context are inside the harness.
What is the difference between guardrails and verification?
A guardrail stops a bad action before it takes effect; verification judges the finished result. The comparison table shows both next to the eval harness.
How do I know whether my harness is working?
Build an eval: a fixed set of test cases, each run several times, with a pass rate you can compare after every change. Add traces so you can replay a failed run. I ran my three-version test twice, 30 runs per version each time, and the exact counts moved between the two batches (23 and 20 valid layouts with no checker, for example). That is enough to see a large gap, such as no checker against checker, but not to rank two versions that differ by a single layout, so use more runs when the differences are small.
Should I use one agent or several?
Start with one. Several agents pay off when the work splits into pieces that can run at the same time, and cost much more in tokens. The multi-agent section has the numbers.
Terms used in this post
- Agent
- A language model that decides its own next step, such as which tool to call, in a loop until it judges the task done.
- Harness
- Everything around the model that makes it usable: the loop, tools, context, rules, checks and logs. The model is the engine; the harness is the rest of the car.
- Guardrail
- A rule enforced by ordinary code before an action takes effect, so a bad action is stopped instead of fixed later.
- Verification
- Judging the finished result against something the agent cannot influence, such as a test that counts missing items.
- Checker
- Ordinary code that checks a proposal against hard rules. It does not guess; it is right or wrong.
- Compaction
- Summarising a long conversation so a new context window can start with the important parts.
- Tool
- A function the model can ask the program to run, such as “place this bed here”. The model decides when to call it; the program does the work and returns the result.
- Loop engineering
- A new, loosely defined term for designing the repeating cycle around an agent: what starts a pass, how each pass is checked, what counts as progress and what stops it.
- Eval harness
- A different thing with the same word: the test setup that scores an agent over many runs. The agent harness serves users; the eval harness measures the agent harness.
Sources
Claims about other teams’ work come from the posts below, read in November 2026. The planner’s design is from my own project notes and code, and the test results are from my own runs.
- Improving Deep Agents with harness engineering, LangChain, 17 February 2026 (the 52.8% to 66.5% result with the model held fixed)
- A harness is not “everything that isn’t the model”, Futurice, 21 July 2026 (the objection to the common definition, and the guardrail and verification principles)
- Building effective agents, Anthropic, December 2024 (workflows versus agents; keep it simple)
- Writing tools for agents, Anthropic, 11 September 2025 (few sharp tools, actionable error messages)
- Effective context engineering for AI agents, Anthropic, 29 September 2025 (context rot, compaction, notes outside the window)
- Effective harnesses for long-running agents, Anthropic, 26 November 2025 (progress files, feature lists, end-to-end checks)
- How we built our multi-agent research system, Anthropic, 13 June 2025 (when multiple agents pay off, and what they cost)
- AI agent guardrails vs. evals, Arize (guardrails act during a run, evals judge performance across runs)
- Loop Engineering for AI Agents, Analytics Vidhya, July 2026 (one of several recent write-ups on the term; definitions vary between them)